
/carbon-agentic
Assess how easily AI agents discover, understand, and safely operate a website, API, tool interface, or other artifact. Test machine-readable semantics, documentation and contracts, real task completion, state and recovery, and applicable agent-readiness guidance; publish actionable feedback rather than testing an agent model itself.
 Jay · Your AI test managerAI evaluations
When to use it
Other AI agents need to discover and operate your interface safely.
Before you start
Inspect semantic labels, contracts, task completion, state recovery and confirmation boundaries. This assesses the target interface, not a universal intelligence score for an agent model.
Try this in your coding agent.
/carbon-agentic Assess whether an AI agent can understand and safely navigate the product catalog.Replace sample paths with your project. Slash names are shorthand; your host may use a plugin prefix or a skill picker. Invocation help →
ILLUSTRATIVE WALKTHROUGH
Agent-operated product catalog
An expanded teaching example, not a recorded or live execution. The report stays visible while the replay explains how to read it.
- 01Read context
- 02Investigate
- 03Show evidence
- 04Report
Coding-agent conversation

Example report
Illustration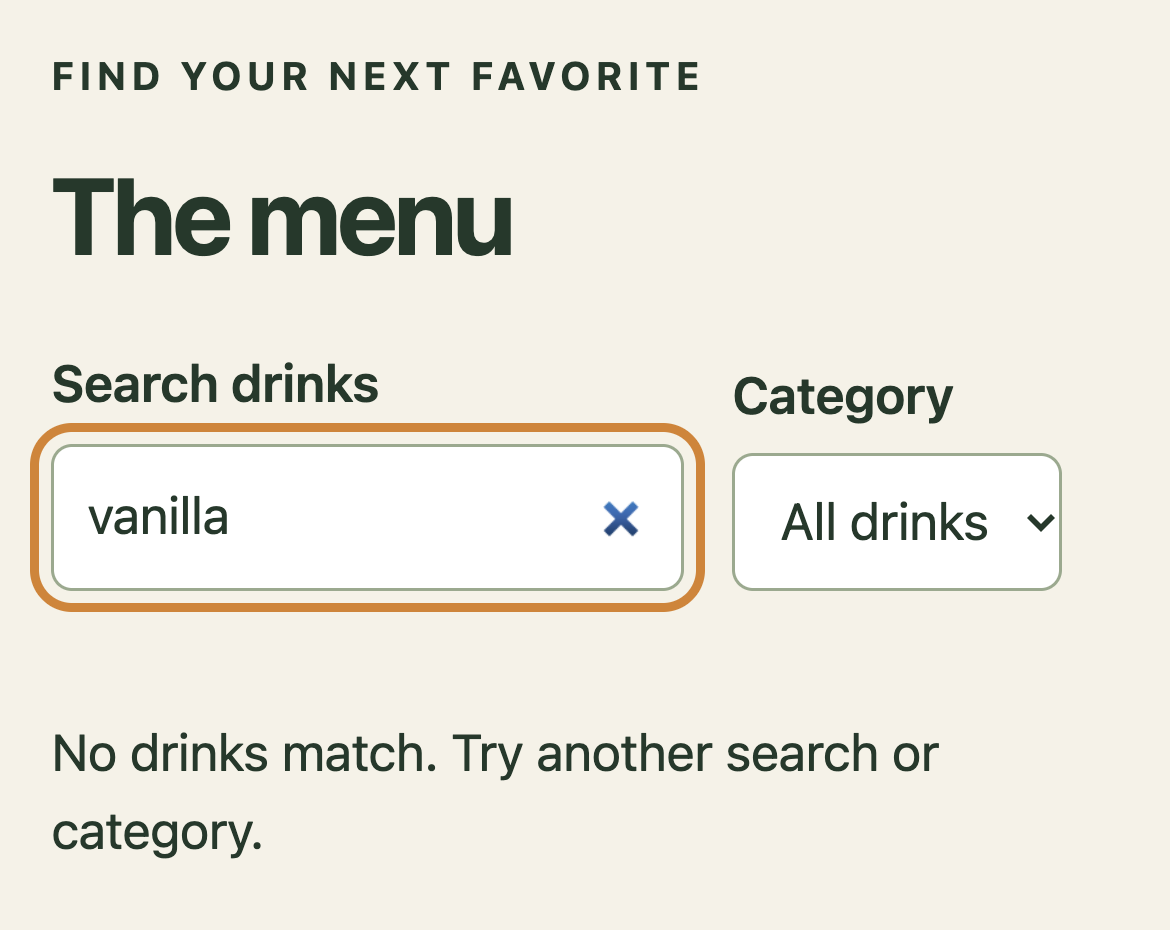
TestBucks course screen with illustrative analysis. The screenshot supplies context; the demo does not establish a newly observed bug.
- Query intent
- Catalog / processing
- Visible result
Illustrated outcome
An unlabeled icon makes a destructive action difficult to distinguish.
Evidence to inspect
Inspect semantic names → discover actions → verify confirmation boundary.
Still untested / not established
Readiness assessment is not a guarantee for every agent.
Ready. Read the full example or play its steps.
What a useful result contains
A bounded claim
For agent-operated product catalog, state the target, revision, environment and actual work performed. Keep planned, executed, blocked and untested work separate.
An inspectable trail
Inspect semantic names → discover actions → verify confirmation boundary. In a real run, retain the source, trace, screenshot or fixture behind the conclusion.
The qualification
Readiness assessment is not a guarantee for every agent.
The next decision
Decide whether the evidence calls for a focused check, a reviewed fix or more context. Do not convert a plausible example into a verified finding.
Adapt the example to your project
- Replace agent-operated product catalog with a real feature, path or decision in your project.
- State the expected rule and its source. Include safe fixtures, constraints and a budget where appropriate.
- Ask for exact evidence and remaining gaps. Approve consequential actions separately.
/jay Review the /carbon-agentic result. Separate observed evidence, assumptions and untested scope, then recommend the next useful check.Where to go next
/carbon-api →/carbon-accessibility →Content checked against the local command definition: skills/carbon-agentic/SKILL.md. Examples adapted from the homepage’s TestBucks walkthroughs. Availability is edition- and host-dependent.